Crawler access
Which crawlers reach this site, and what they ask for once they arrive. These notes count requests in the server log instead of trusting user-agent strings: AI crawlers checked against the IP ranges their owners publish, the Markdown and llms.txt files served to agents, and what an agent readiness score actually measures. Every number comes from requests you can repeat. They show what machines can reach, not a promise that any engine will cite a page.
 By John Patzi 7 notes
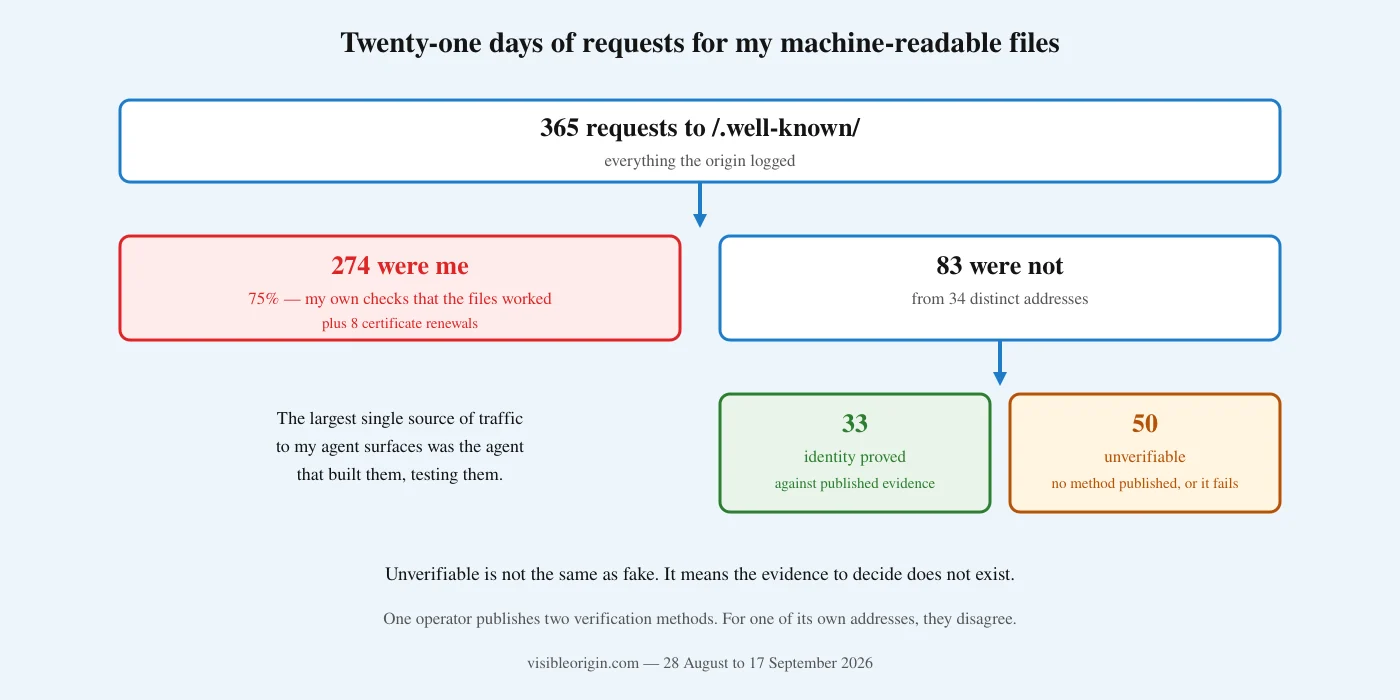 Crawler access I publish six .well-known files. 89% of the traffic to them was meTwenty-one days of requests for this site's machine-readable files, with my own traffic removed and every remaining identity checked against what its operator publishes. 365 requests, 274 of them mine, 33 proved.Read the note
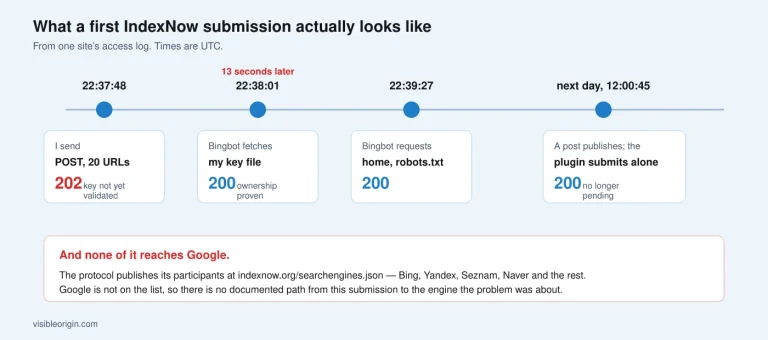 Crawler access I turned on IndexNow to fix a Google problem. Google is not in the protocolGooglebot was crawling almost none of my posts, so I enabled IndexNow and watched Bing fetch my key file thirteen seconds later. It worked exactly as documented, and it cannot touch the problem I turned it on for.
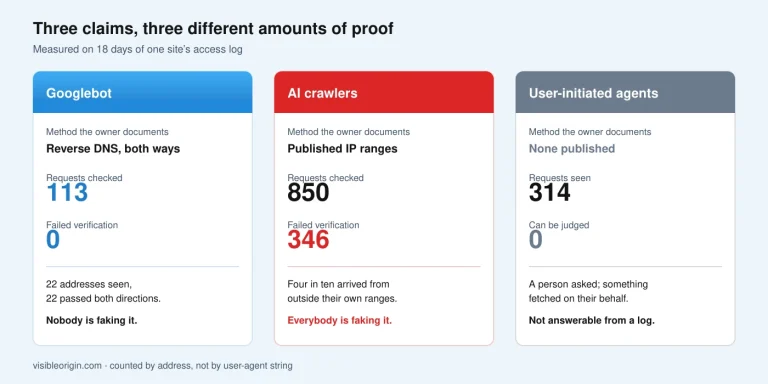 Crawler access 346 requests said they were AI crawlers. Their owners’ IP ranges said otherwiseI counted AI crawler traffic the way everyone counts it, by user-agent string, and was about to publish the number. Then I checked every address against the ranges each operator publishes for its own crawler.
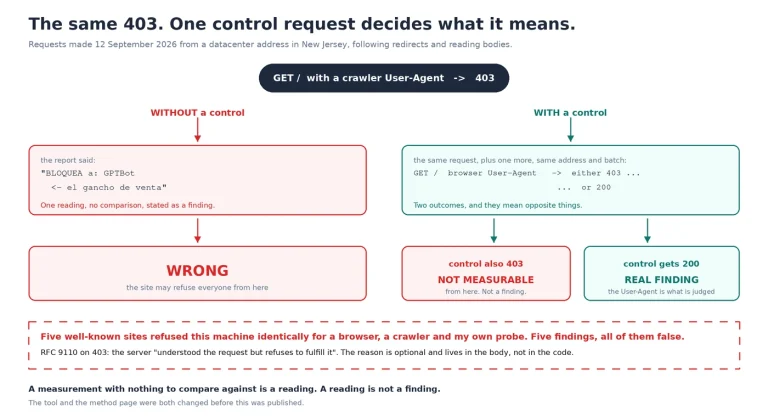 Crawler access My free check runs from a datacenter, and today I measured what that costs itFive well-known sites refused this machine identically whether I claimed to be a browser, a crawler or my own probe. My tool was reporting exactly that as evidence the site blocks crawlers, and calling it the sales hook. Fixed, then written up.
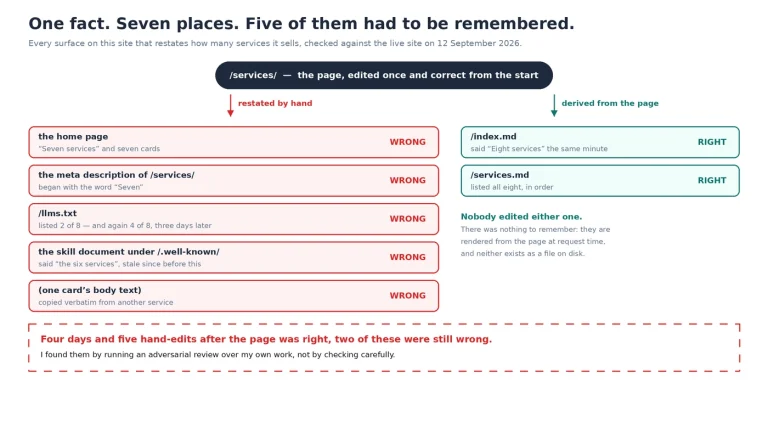 Crawler access I changed one number on one page, and five other places went on saying the old oneTaking a catalogue from seven items to eight took four days and five hand-edits, and two of them were found by an adversarial review rather than by me. The only surfaces that stayed correct were the two nobody had to remember.
 Crawler access An agent readiness score gave my site Level 5 for failing its only checkThree requests to the same scanner in one minute, for the same site, returned Level 5, Level 4, and Level 5 with a score of zero. A preset from its own dropdown returns 100. Here is where each number comes from.
 Crawler access Two ways to serve Markdown to agents, and each one fails quietlyThis site publishes every page twice: once as HTML, once as Markdown. Choosing between content negotiation and a parallel .md route is not a style question — each one fails silently, in a different way. Here is what I measured on my own server and on Cloudflare's.